
CodingSoftware & developer tools
Datasette 1.0a43 opens exports to plugins, and datasette-arrows streams SQLite data as Apache Arrow
Datasette 1.0a43 added streaming output renderers for plugins. The alpha datasette-arrows plugin uses them to export full SQLite tables or query results as Apache Arrow IPC streams, page by page. Claude Fable 5.2 is credited with much of the work.
From the Simon Willison article of November 18, 2026 and cited sources: Datasette 1.0a43 rebuilt its CSV and TSV streaming as a general mechanism that plugins can use. [3] [4] [7]
SOURCES[3] Datasette changelog docs.datasette.io[4] Simon Willison: Datasette 1.0a43 simonwillison.net[7] newreleases.io: Datasette 1.0a43 newreleases.io
 AT Pulse research deskPublished · Updated · 4 min read · AI-assisted analysis
AI-assisted, not human-edited. Methodology Corrections Who owns this site
- What happened
- Datasette 1.0a43 rebuilt its CSV and TSV streaming as a general mechanism that plugins can use. [3] [4] [7]
- Original source
- Simon Willison article, independent perspective
- Brief by
- AT Pulse research desk AI-assisted; publisher and contact on the desk page
- When
- November 18, 2026 article published
- Covered
- Nov 21 edition
- Evidence
- 9 sources across 7 sites
Reach: not measured yet
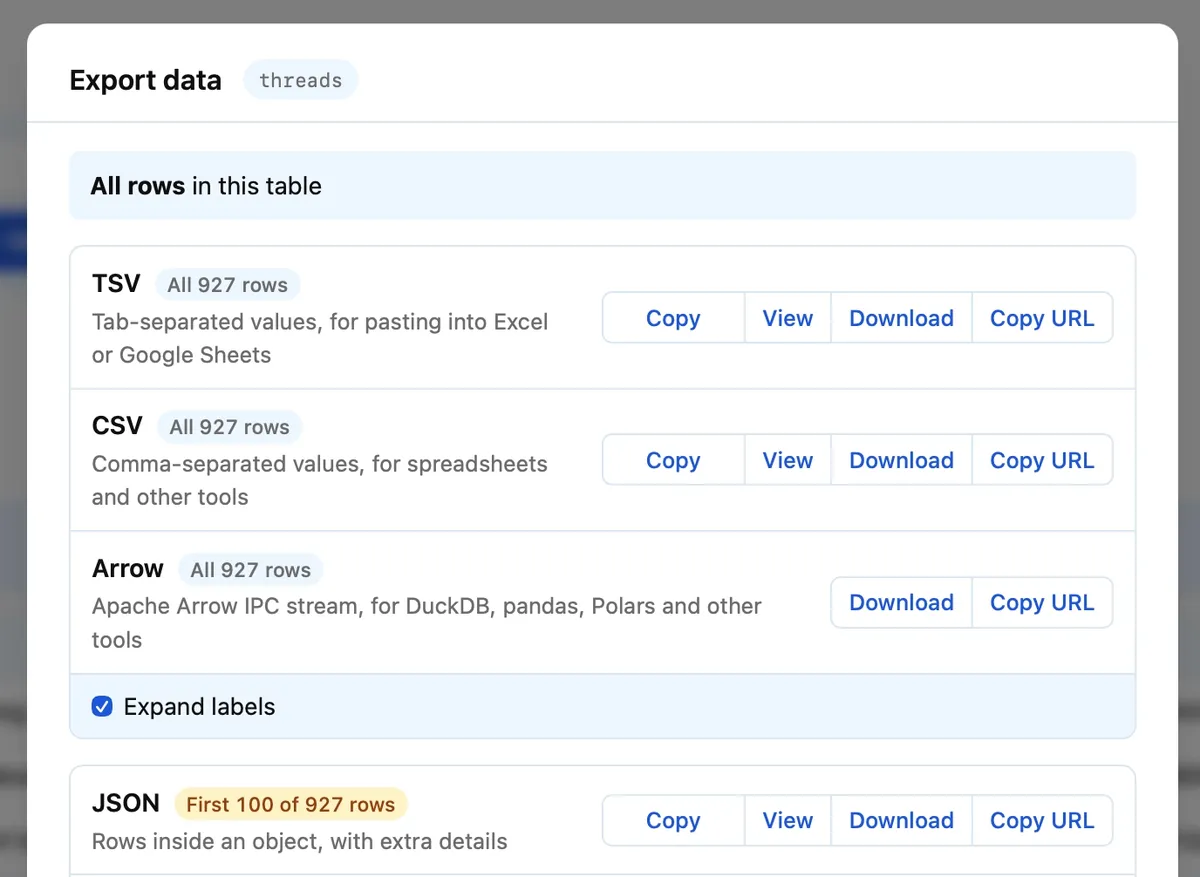
Datasette 1.0a43 rebuilt its CSV and TSV streaming as a general mechanism that plugins can use. A renderer that accepts a row_stream argument and returns Response.stream() receives every row when ?_stream=1 is in the URL. Renderers that still return the old dict format now raise an error. [3] [4] [7]
datasette-arrows adds .arrows endpoints for tables and SQL queries. Each page of rows goes out as one Arrow record batch, so the full result never has to be held in memory. DuckDB, pandas and Polars can read the output directly as typed columns. [2] [5] [8] [9]
The plugin fixes the schema from the declared SQLite column types and the values in the first page. If a later row holds a value that doesn't fit, such as text in an INTEGER column, the stream disconnects partway through. The documented workaround is to cast the column in SQL. [2]
Simon Willison says Claude Fable 5.2 suggested using Arrow's streaming format and wrote the plugin almost in a single pass. That account comes only from the author, and no prompts or session logs have been published. [1]
Typed Arrow output lets data teams load SQLite-backed data into DuckDB or DataFrames without parsing CSV. The memory and speed benefits follow from the design but no one has measured them.
Read the full assessment
The build also shows a model contributing design choices, not only code.
Executive brief
Datasette 1.0a43 opened the export system to plugins, and datasette-arrows 0.1a0 is the first plugin to use it. The notable part is how it was built: Simon Willison says Claude Fable 5.2 proposed Apache Arrow's streaming format and wrote the plugin "in almost a single shot" (Willison). The plugin exports whole SQLite tables or query results as Arrow IPC streams, one page of rows at a time, so the full result never has to sit in memory (README). It is an alpha release. No reviewed source has tested its performance, and only an AI-model attribution from the author backs the "single shot" claim.
What changed and event timeline
Datasette 1.0a42 ships
It brought a homepage redesign, column statistics and TSV export. It is also the last release affected by a private stored-query exposure bug that started in 1.0a31 ().
1.0a43 adds streaming output renderers
CSV and TSV now run on a general streaming mechanism built on
Response.stream(). The release also fixes three security issues. Willison says he is "leaning hard" on Claude Fable 5.2 to reach 1.0 (;).Datasette-arrows 0.1a0 released
A pre-release that adds a
.arrowsstreaming export for tables and queries. It exists to show the new hook working, following Willison's rule of never shipping a plugin feature without a plugin that uses it (;).- Also
Next alpha (no date): export dialog regrouping
The main branch already lists Arrow next to CSV and TSV under "All rows in this table". The current release does not ().
Capabilities and access
- Needs datasette ≥1.0a43 and pyarrow (explainx summary).
- Without
?_stream=1you get one page of rows; with it you get every row. The MIME type isapplication/vnd.apache.arrow.stream(README). - Type mapping: integers become int64, floats or mixed numbers float64, text string, blobs binary, and columns that are all null with no declared type become string (README).
Read the full section
- Install:
datasette install datasette-arrows. Needs datasette ≥1.0a43 and pyarrow (explainx summary). - Endpoints:
/db/table.arrowsand/db/-/query.arrows?sql=…. Without?_stream=1you get one page of rows; with it you get every row. The MIME type isapplication/vnd.apache.arrow.stream(README). - Type mapping: integers become int64, floats or mixed numbers float64, text string, blobs binary, and columns that are all null with no declared type become string (README).
- Model named: Claude Fable 5.2 (Willison).
Technical analysis for researchers and developers
- Hook design: a renderer that accepts a
row_streamargument and returnsResponse.stream()receives every row whenever?_stream=1is in the URL (changelog). - How rows go out: each page of rows becomes one Arrow record batch (README).
- Schema inference: the schema is fixed from the declared SQLite column types plus the values in the first page.
Read the full section
- Hook design: a renderer that accepts a
row_streamargument and returnsResponse.stream()receives every row whenever?_stream=1is in the URL (changelog). Renderers must now return aResponseorNone. The old dict return, deprecated since 0.49, now raises an error (newreleases). - How rows go out: each page of rows becomes one Arrow record batch (README). Arrow's streaming format sends a schema message first, then record batches, then an optional end-of-stream marker. Readers must go through it in order, with no random access (Arrow spec).
- Schema inference: the schema is fixed from the declared SQLite column types plus the values in the first page. It cannot change once streaming starts.
- Tests: they run with
uv run pytest, and GitHub Actions workflows are present (README).
Claims and evidence
- Claim: Fable 5.2 suggested Arrow and built the plugin almost single-shot. No prompts or session logs are published.
- Claim: memory-bounded export. This follows from the page-per-batch design (README), but no published measurement checks it.
- Claim: Arrow beats CSV for large tables.
Read the full section
- Claim: Fable 5.2 suggested Arrow and built the plugin almost single-shot. The only evidence is the author's own statement (Willison). No prompts or session logs are published.
- Claim: memory-bounded export. This follows from the page-per-batch design (README), but no published measurement checks it.
- Claim: Arrow beats CSV for large tables. Secondary coverage gives rules of thumb, such as more than 20 columns or more than 1M rows, without benchmark data (explainx).
- Independent corroboration: none in the reviewed sources.
Context and prior work
- Datasette has streamed CSV for a long time. 1.0a43 turned that into a general mechanism (Willison on 1.0a43).
- Arrow IPC streams can be read directly by common tools.
- Willison posted the day before about running Datasette in the browser with Pyodide, part of the same push on 1.0 infrastructure (Willison).
Read the full section
- Datasette has streamed CSV for a long time. 1.0a43 turned that into a general mechanism (Willison on 1.0a43).
- Arrow IPC streams can be read directly by common tools. DuckDB added Arrow IPC support in May 2025 (DuckDB), and pandas and Polars also read the format.
- Willison posted the day before about running Datasette in the browser with Pyodide, part of the same push on 1.0 infrastructure (Willison).
Limitations, safety and contested findings
- If a later page holds a value that doesn't fit the inferred schema, such as text in an INTEGER column, the export fails by disconnecting partway through.
- Conflicting sources: the README says streaming renderers are only on Datasette's main branch and not yet in a release (README).
- Security context: 1.0a43 fixed a bug where anyone, including anonymous users, could see private stored-query titles and SQL.
Read the full section
- If a later page holds a value that doesn't fit the inferred schema, such as text in an INTEGER column, the export fails by disconnecting partway through. The workaround is to cast the column in SQL (README).
- Conflicting sources: the README says streaming renderers are only on Datasette's main branch and not yet in a release (README). The changelog and the plugin's stated requirements say 1.0a43 includes them (changelog).
- Security context: 1.0a43 fixed a bug where anyone, including anonymous users, could see private stored-query titles and SQL. It also fixed a database-download permission bypass (changelog).
Business and practitioner implications
- Data teams: you can pull large SQLite-backed datasets straight into DataFrame or DuckDB workflows as typed columns, with no CSV parsing step.
- Plugin authors: pinning to 1.0a43 means adopting the new
Responsecontract and the change to row JSON format. - Engineering leaders: this is a concrete case of a maintainer using a frontier model for both design suggestions and implementation.
Read the full section
- Data teams: you can pull large SQLite-backed datasets straight into DataFrame or DuckDB workflows as typed columns, with no CSV parsing step. Version, cast and test columns first, because a type surprise partway through ends the export.
- Plugin authors: pinning to 1.0a43 means adopting the new
Responsecontract and the change to row JSON format. - Engineering leaders: this is a concrete case of a maintainer using a frontier model for both design suggestions and implementation. It is a single anecdote reported by the developer, not a measured productivity result.